 Java
Overview
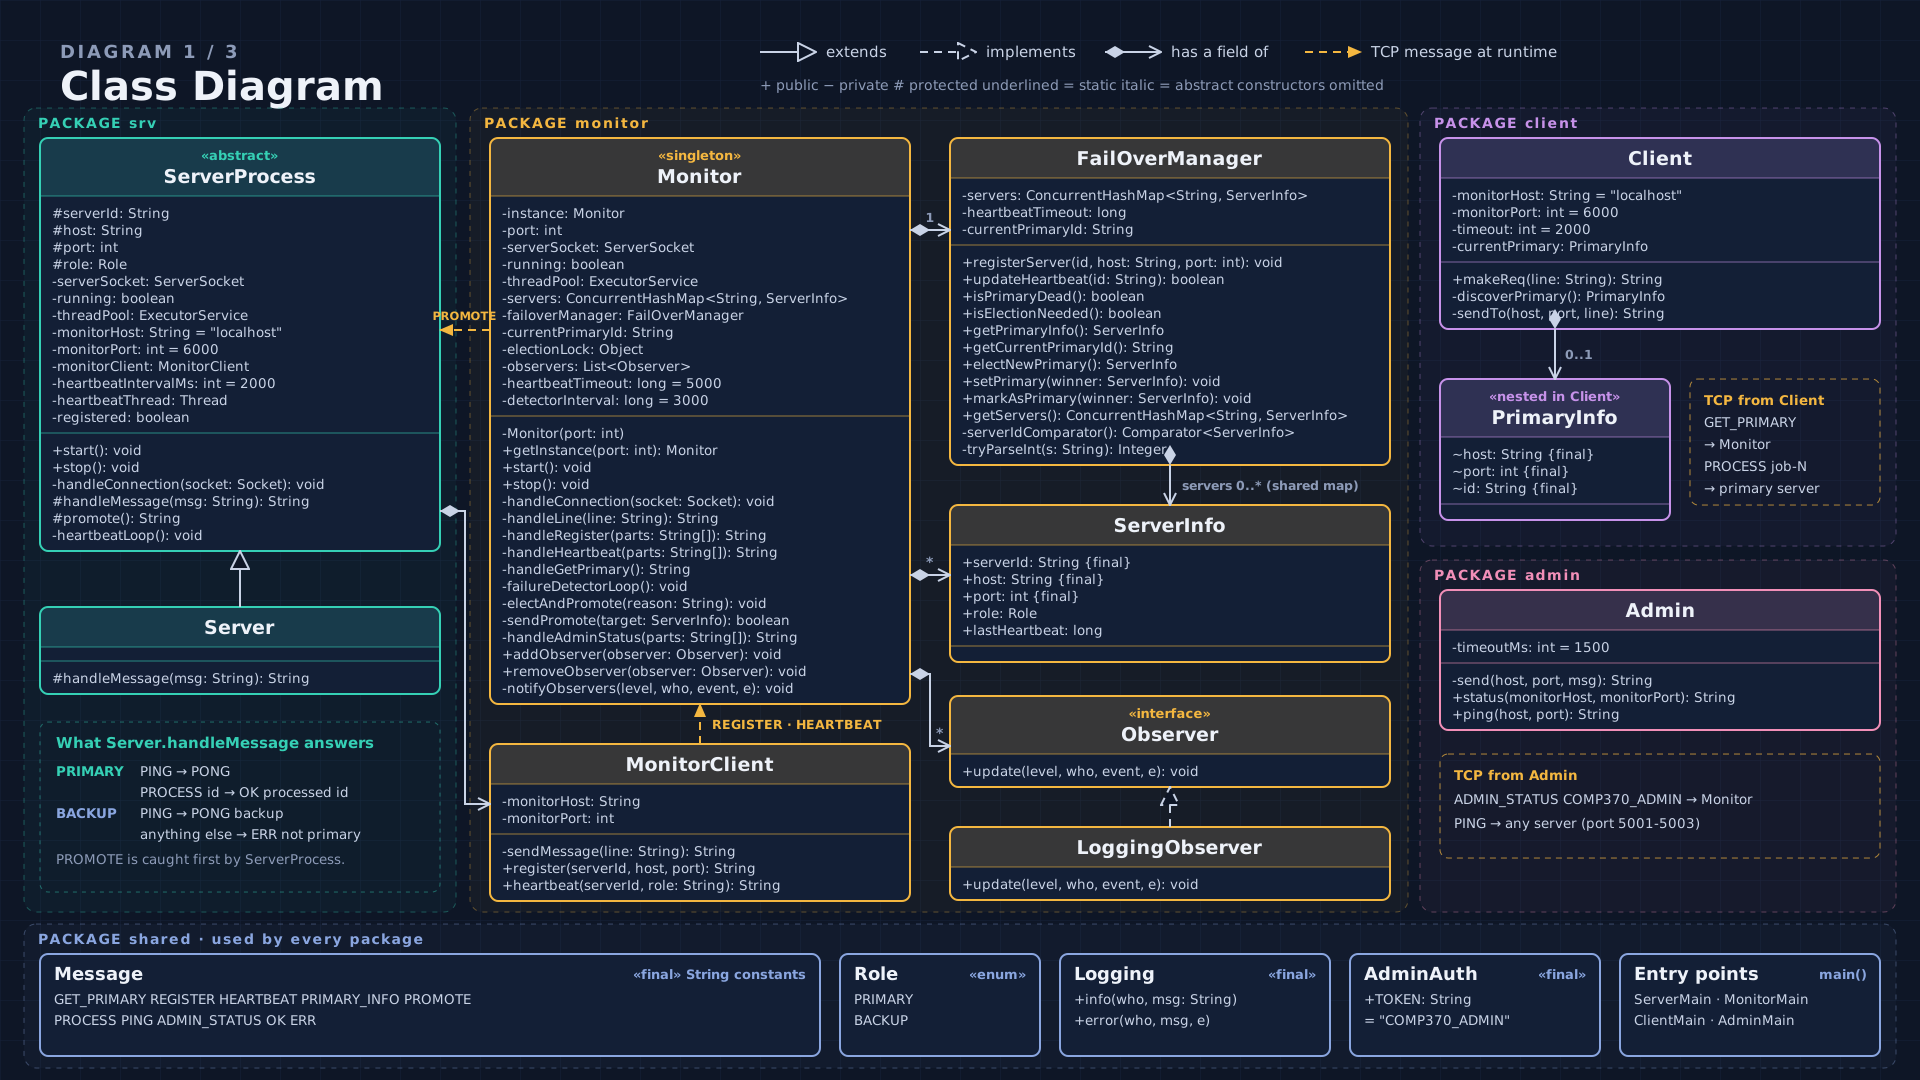
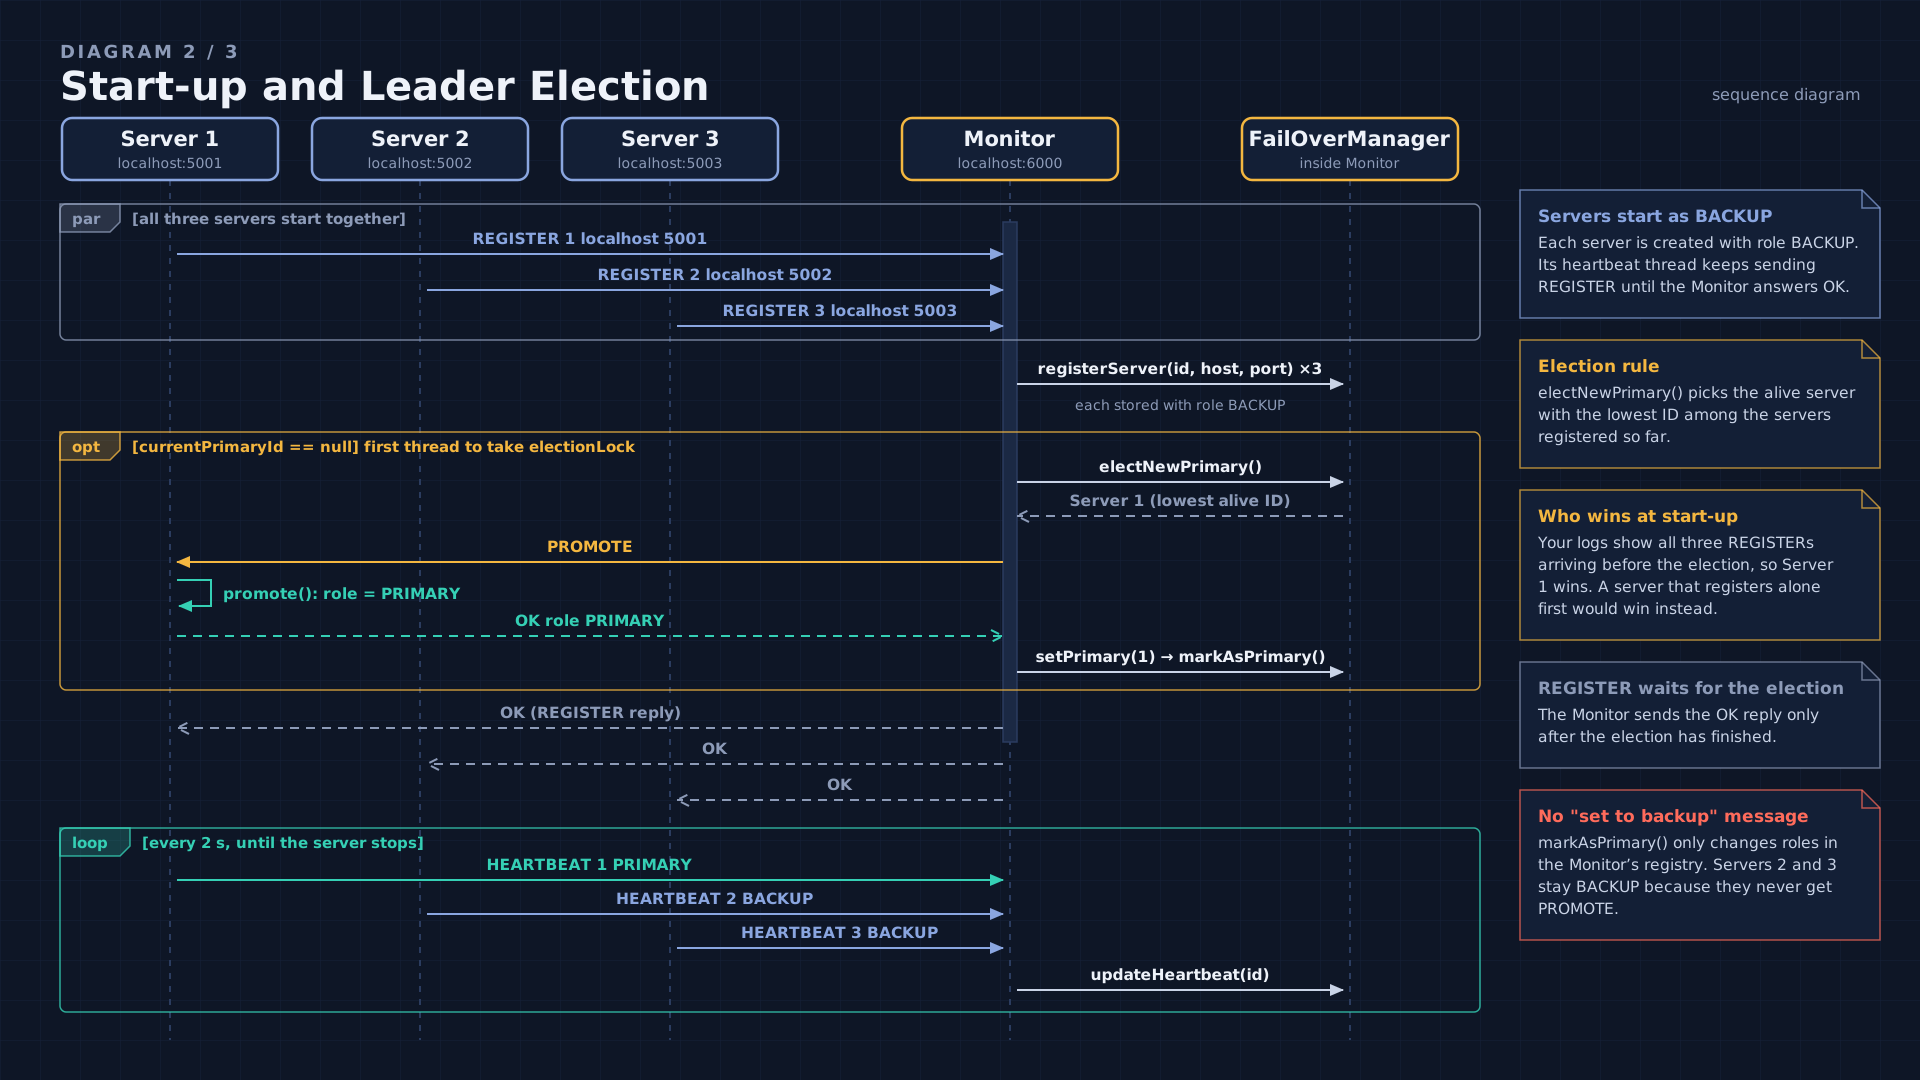
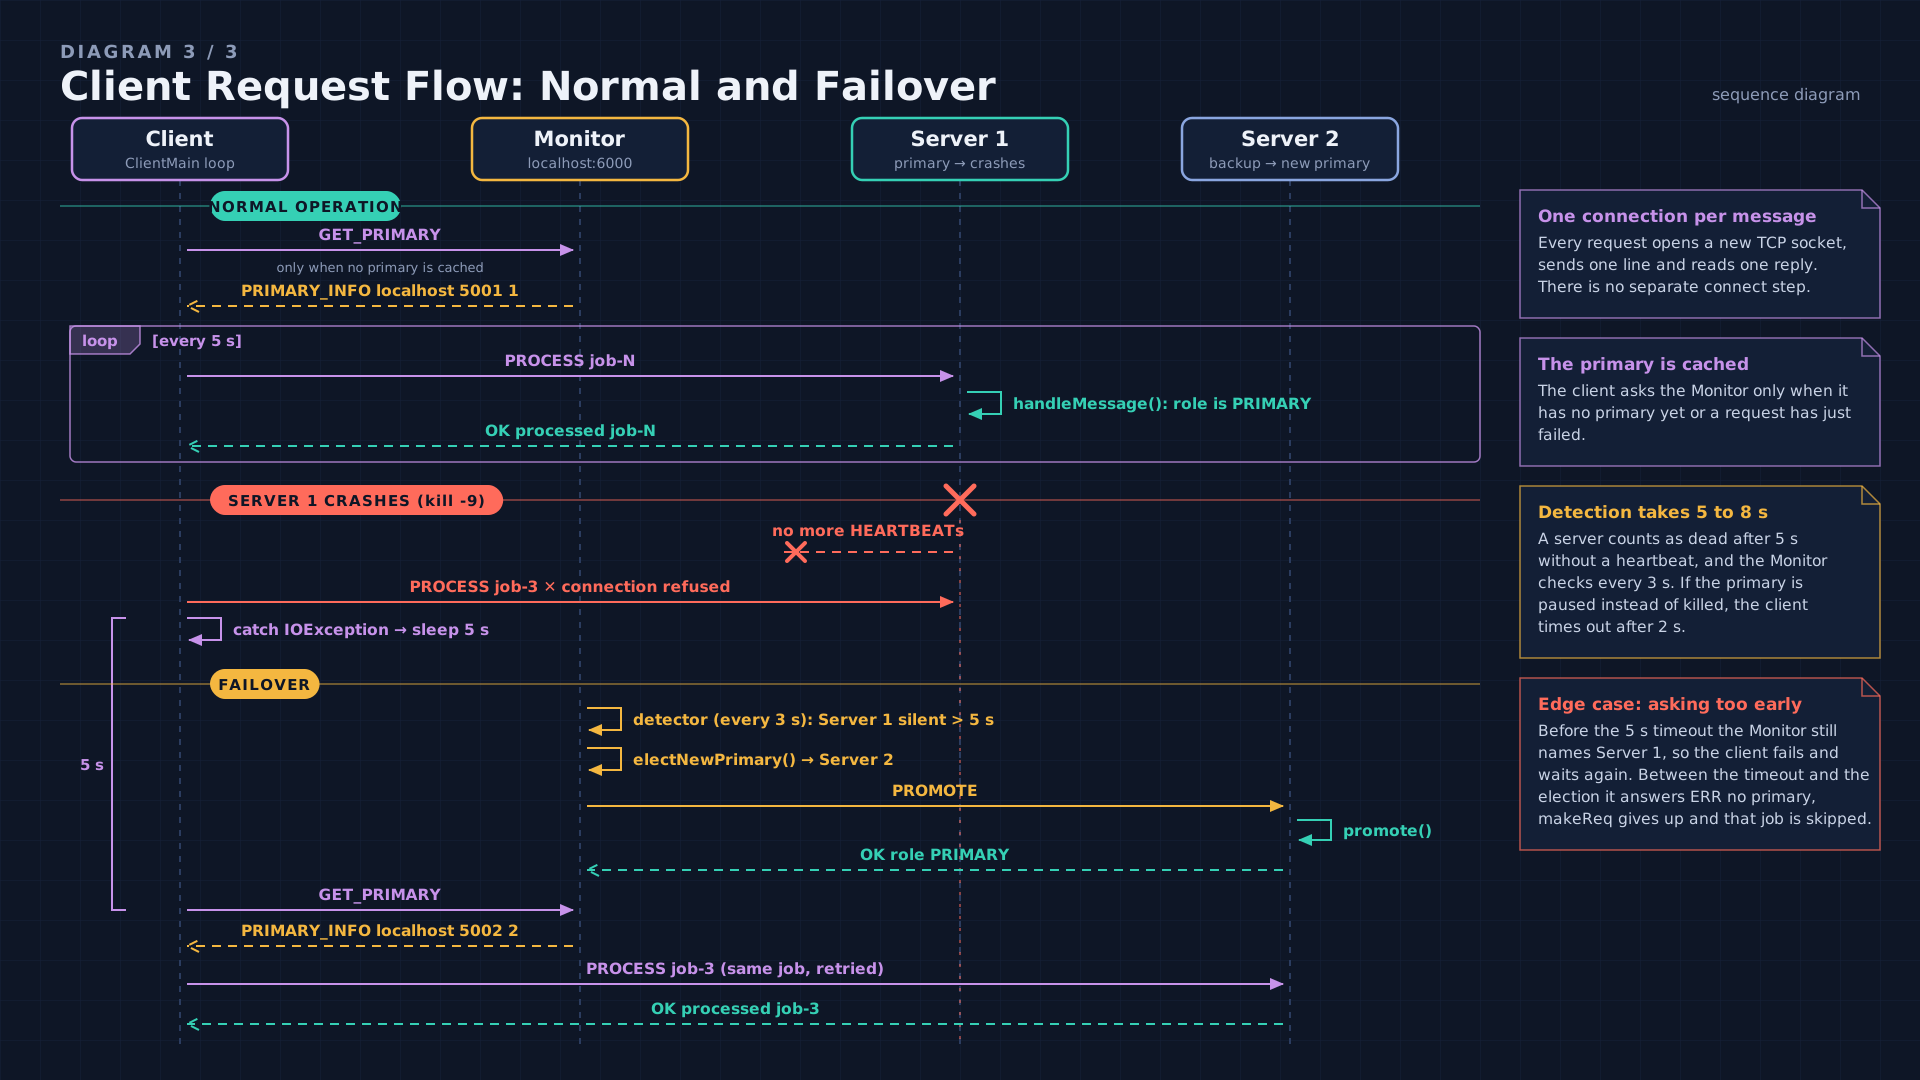
A primary-backup server cluster that runs across multiple JVM processes and keeps serving when the primary fails. Built from January to April 2026.
What I built
- Automatic failover with heartbeat-based failure detection and deterministic leader election.
- Communication between nodes over multithreaded TCP sockets.
- The Singleton, Observer and Abstraction–Occurrence design patterns.
Results
I simulated real-world failures against the cluster, and failover recovery takes under 2 seconds.